Loading post…
Introduction to Gradient Descent and Backpropagation
Gradient descent, derivatives, and backpropagation from scratch
Welcome to My Machine Learning Journey!
This is my very first blog post and I am really excited to share it with you!
Even though I am extremely motivated to write about all the cool stuff I am learning at the moment, I will also ask you to be patient with me as this is a completely new experience for me. I will try my best to make it as enjoyable and informative as possible for you!
The Secret Engine Behind AI
Have you ever wondered what makes all those impressive AI models actually work? Today I'm diving into the underlying foundation of machine learning, on which ALL of today's neural networks are built - whether it's:
- CNNs (Convolutional Neural Networks - the ones that recognize images)
- Transformers (the technology powering ChatGPT and other language models)
- Diffusion models (creating those amazing AI-generated images)
- GANs (Generative Adversarial Networks - making fake photos look real)
- Or even a simple network with just a few layers
Why This Matters
I know this topic has already been covered extensively by others - and there are some really GREAT sources out there. For example, the video on gradient descent by 3blue1brown, who makes fantastic videos about math in general (which, as you might have guessed, often relates directly to machine learning). Another excellent resource is the video by Andrej Karpathy on backpropagation, where he builds the basic building blocks of AI libraries like PyTorch and TensorFlow from scratch. But I wanted to share my own journey with gradient descent because understanding this concept was one of my personal "aha!" moment - the point where machine learning started to make sense to me as more than just magic, while at the same time actually being very magical (and simple as well)! Enough of the introduction, let's get started!
What Are Neural Networks
Many people will probably tell you that neural networks basically work like a simplified human brain, which is correct, but for me personally, it felt way more intuitive to think of them as simple mathematical functions that take some input and produce an output. This is in fact how they are built in the first place! For this post, we are just gonna use a very, very, very small neural network but act as if it was 1.000.000 times bigger, because for understanding the concept of them, it actually doesn't matter how many layers or neurons we have. The principles stay exactly the same!
From Real-World Data to Numbers
Let's break this down with some examples:
- Images: That cute cat photo you took? To a neural network, it's just a giant list of numbers representing how bright each pixel
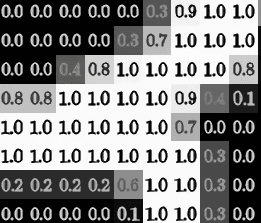 is (usually from 0-255 for each red, green, and blue channel)
- Audio: Your favorite song? Just a sequence of numbers showing the sound wave's amplitude at each moment
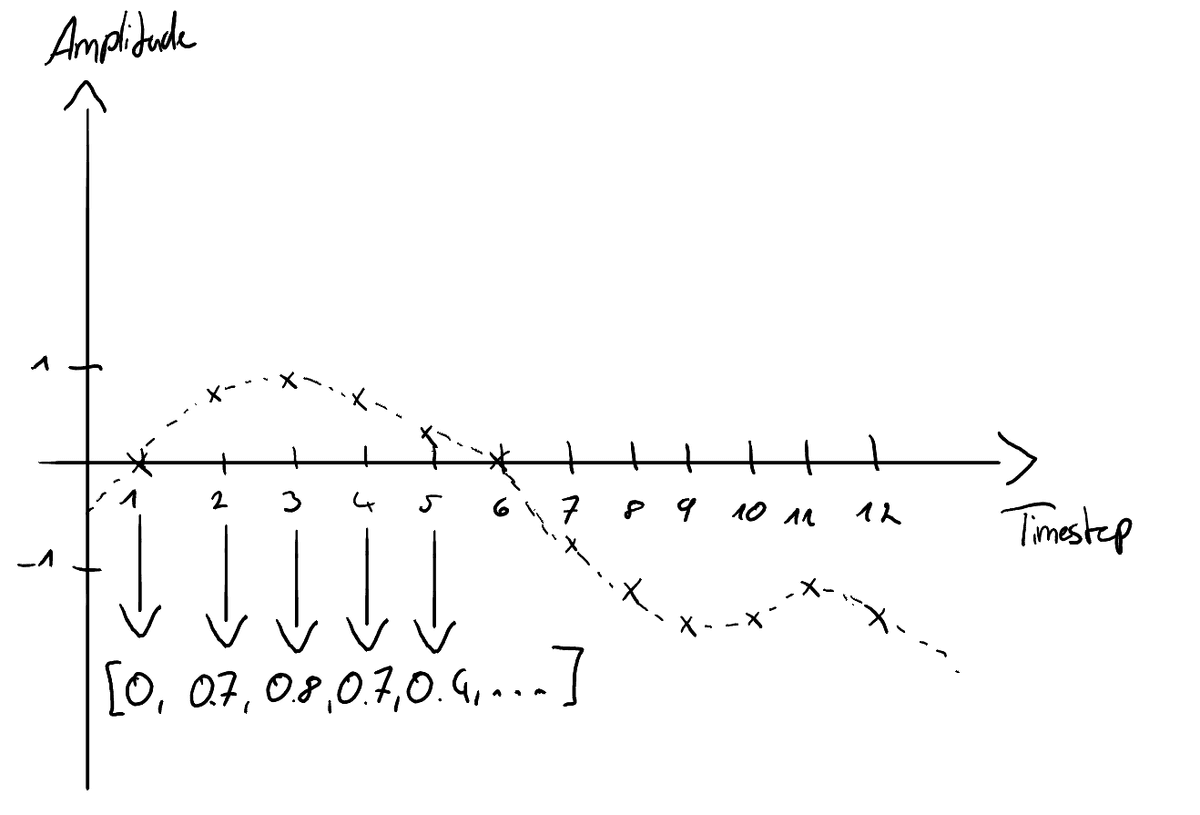
- Text: This blog post? Each word gets converted to a number (or vector of numbers) that represents its meaning
This input
This function takes our input vector
Why This Simplified View Helps
When I stopped thinking about neurons firing and started thinking about functions transforming numbers, everything about machine learning suddenly became clearer. It removed all the mystery and made me realize: "Hey, this is just math I can actually understand!" In the next sections, I'll show you exactly how these mathematical functions work and how gradient descent helps them learn. Don't worry if you're not a math person - we'll keep it visual and intuitive!
Example: House Price Prediction
Let's make this concrete with a real-world example that most of us can relate to. Imagine we want to train a neural network to predict the price of a house based on just two factors: its size (in square feet) and the year it was built. This is something we could actually use in real life, right? This simple case can be represented as a function that takes two inputs (size and year) and produces one output (price - don't worry I will also later on address multiple outputs!). To make it even easier to understand, let's say we have just one hidden layer between the input and output. Here's what this simple neural network looks like:
$ hover a neuron to trace its weights, click it for its formula
// neural network architectureInput Layer
Hidden Layer 1
Output Layer
Size
Year Built
H1_1
H1_2
Price
● neuron— connectionw weight (shown on hover)◯ selected
Why is this tiny example so powerful? Because even the most advanced neural networks—the ones with billions of parameters that power ChatGPT or generate photorealistic images—follow this exact same pattern! They just have many more inputs, hidden layers with thousands of neurons. The beauty is that once you understand how our little house price predictor works, you've actually grasped the fundamental concept behind all neural networks, no matter how complex they get.
"Weights" of a Neural Network
So when passing our input vector
For our house example with size=140, year=1998, weights=[-0.5, 2], and bias=3:
Mathematicians write this more elegantly using the sum symbol:
This simple formula powers every neural network on earth! Whether it's ChatGPT writing essays or DALL-E creating art, they're all doing this calculation billions of times with different inputs and weights.
To be completely transparent, there actually also is another additional step to calculate the activation of a neuron, which is
called the activation function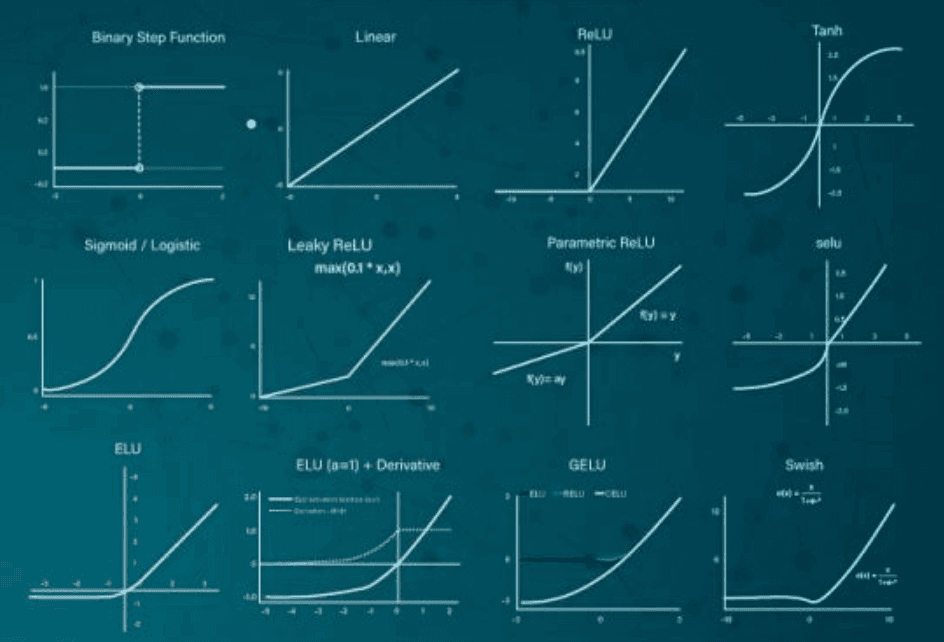 . This function takes the output of the neuron and applies one of many transformations to it, which implements additional stability to the model. The most common activation functions are the sigmoid function, the hyperbolic tangent function (tanh), and the rectified linear unit (ReLU). This would leave us with the following formula:
where
For our example, we will just ignore this step for now to keep it simple and doesn't really have an impact on the principle of backpropagation itself. But if you want to learn more about it, I highly recommend checking out the link I provided above! The real question is: how do these random weights transform into smart predictions? I mean - our previous model prediction of 3929$ is obviously not the price of a house (even though anyone of us wouldn't mind getting a house for that price), right?
How Do We Know If Our Model Is Any Good?
We need some way to measure how well (or poorly!) our neural network is performing. The Loss Function can be seen as the report card for our AI model! This function has one job: tell us how far off our prediction is from the actual correct answer. For our house example, imagine the actual price is $100,000, but our model predicted $3,929. Yikes - that's way off! The smaller the loss, the better our model is doing. There are many loss functions out there, but for our example, we'll use the most common one for regression problems: the Mean Squared Error (MSE). Here's how it looks mathematically:
Where
Let's plug in our numbers:
That is indeed a huge number. In this case actually - these values are expected to be large when dealing with this kind of data. The squaring in MSE intentionally punishes bigger mistakes more severely. If our prediction was off by twice as much, our error would be four times bigger! If our model had perfectly predicted $100,000, our MSE would be exactly 0 - which would be a perfect score! That's our goal. But how do we get from our terrible prediction to a good one? How do we teach our neural network to adjust those random weights to make better predictions? That's where "gradient descent" comes into play!
Optional: Vector outputs
Don't worry, I haven't forgotten about the multiple outputs! In the real world, neural networks rarely have just one neuron in the output layer - they usually have several or even thousands, depending on what we're trying to accomplish. Let's take the classic MNIST dataset as an example - it's like the "Hello World" of machine learning! This dataset contains 28×28 pixel images of handwritten digits from 0 to 9. Here's how our neural network would handle this:
- Input layer: 784 neurons (28×28 pixels), each representing the brightness of one pixel (from 0-255)
- Hidden layers: Could be any number, depending on how complex we want our model to be
- Output layer: 10 neurons, one for each possible digit (0-9)
Unlike our house price example that gave us a single number, this network outputs a vector of 10 values that looks something like:
Each number represents the model's "confidence" that the image belongs to that class. In this example, the highest value (0.75) is in the 5th position, meaning our model is 75% confident that the image shows the digit "4". When we train this model, our loss function now measures how far this entire output vector is from the correct answer. For example, if the image actually shows a "4", the perfect output would be:
The beauty is that whether we're predicting a single house price or classifying images into 10,000 different categories, the core mechanism of training with gradient descent remains exactly the same! The mathematics scales perfectly from simple to incredibly complex problems - that's why deep learning is so powerful!
$ hover a neuron to trace its weights, click it for its formula
// digit classifierInput Layer
Hidden Layer 1
Hidden Layer 2
Output Layer
Pixel 1
Pixel 2
...
Pixel 784
H1_1
H1_2
H2_1
H2_2
H2_3
Digit 0
Digit 1
...
Digit 9
● neuron— connectionw weight (shown on hover)◯ selected
Back to the Loss (Calculus)!
So we've measured how bad our prediction is with our loss function. But the million-dollar question is: how do we actually make our model better? How do we go from "wildly wrong" to "impressively accurate"?
We know we want to minimize our loss value. The closer to 0, the better! But how do we adjust those weights and biases to get there?
Time to pull out those high school calculus books! Remember when you asked, "When am I ever going to use this in real life?" Well, surprise — the time has come!
Derivatives: The Key to Neural Network Learning
Since we track our computational graph (the math operations that led to our loss), we can calculate how each weight and bias affects our final loss. This process is called backpropagation — the mechanism that enables neural networks to learn.
What's a Derivative?
A derivative measures how a function's output changes when we slightly modify its input. In the context of neural networks, it tells us how the loss changes when we adjust a specific weight or bias.
Think of the derivative as the slope of a function at a particular point. If you're on a hill, the derivative tells you which way is downhill and how steep it is — exactly what we need to minimize our loss.
What even does "With Respect To" Mean?
In calculus, we typically work with functions of a single variable like
When we calculate "the derivative of loss with respect to weight
For each parameter in our network, we compute its individual effect on the loss. This gives us a vector of derivatives called the gradient, which indicates how to adjust every parameter to reduce our loss.
From Gradients to Learning
The gradient points in the direction of steepest increase in the loss. To minimize loss, we move in the opposite direction:
Where
This is the essence of gradient descent — the foundational algorithm behind neural network training. By iteratively calculating gradients and updating weights, the network gradually improves its predictions.
So this was a lot of math and theory! Wrapping your head around such high dimensional vectors is just way more abstract than the imaginable 2D or 3D space the human brain is used to. In another Blog post, we will dive deeper into how this backpropagation is actually implemented in practise and how we can use the Chain Rule to calculate the derivatives of our loss function with respect to our weights and biases. Otherwise, I hope you enjoyed this little journey over the hills of calculus and the valleys of loss functions! For those interested in the mathematical details of derivatives and calculus, I've included an optional section below.
Optional Math Section
Let's say we have a function
The derivative is defined as "rise over run" – the change in output divided by the change in input:
Here,
The derivative gives us important informations: it tells us exactly which direction to move our weights to decrease our loss! If the derivative is positive, we need to decrease our weight. If it's negative, we need to increase it.
From Math to Machine Learning
Now imagine this was our loss function:
$ hover the curve to read x, f(x) and f'(x)
// f(x) = x²● f(x)● f'(x) shown on hover
This simple function
- It has a clear minimum point (at x=0)
- It increases as we move away from that minimum in either direction
- It's shaped like a bowl - just like our MSE loss function!
The derivative of
- If x is positive, the derivative is positive (the slope points upward to the right)
- If x is negative, the derivative is negative (the slope points downward to the left)
- At x=0, the derivative is 0 (flat, we've reached the minimum!)
The Bridge to Neural Network Weights
In our neural network, each weight is like a separate dimension in this loss landscape. Instead of a simple 2D parabola, we have a multi-dimensional surface where each dimension corresponds to one weight in our network.
Let's go back to our house price model with weights
- How should we change w₁ to reduce our loss?
- How should we change w₂ to reduce our loss?
Mathematically, we compute the derivative of our loss function with respect to each weight. These derivatives tell us the direction and steepness of the loss landscape for each weight:
Let's say we calculate these derivatives and get:
The negative value for w₁ means: "Increase w₁ to reduce the loss" (because moving in the opposite direction of the derivative reduces the function value) The positive value for w₂ means: "Decrease w₂ to reduce the loss"
This is why we update weights using the formula:
Applying this to our example:
Amazingly, with these new weights, our model will make a prediction that's closer to the actual house price! If we repeat this process many times (thousands or millions of iterations), our weights gradually converge to values that minimize the loss.